Most stable face, hair, scarf, jacket, and pin across all three locations.
Controlled test · September 22, 2026
Which AI video model keeps one character consistent across scenes?
Seedance 2.5 kept Mara Vale's face and wardrobe most stable. MiniMax H3 Max followed the three-shot plan most literally and cost the least. Wan 3.0 built convincing scenes but showed the clearest facial drift. Every model received the same character sheet, the same 11.28-second ElevenLabs voice reference, and the same three-scene brief. These are unedited, first-attempt outputs.
The short answer
The strongest identity match was also the most expensive.
Clear shot structure at 176 credits, with moderate fine-detail drift.
$9.79 for the three 11-second video generations.
Shared character reference
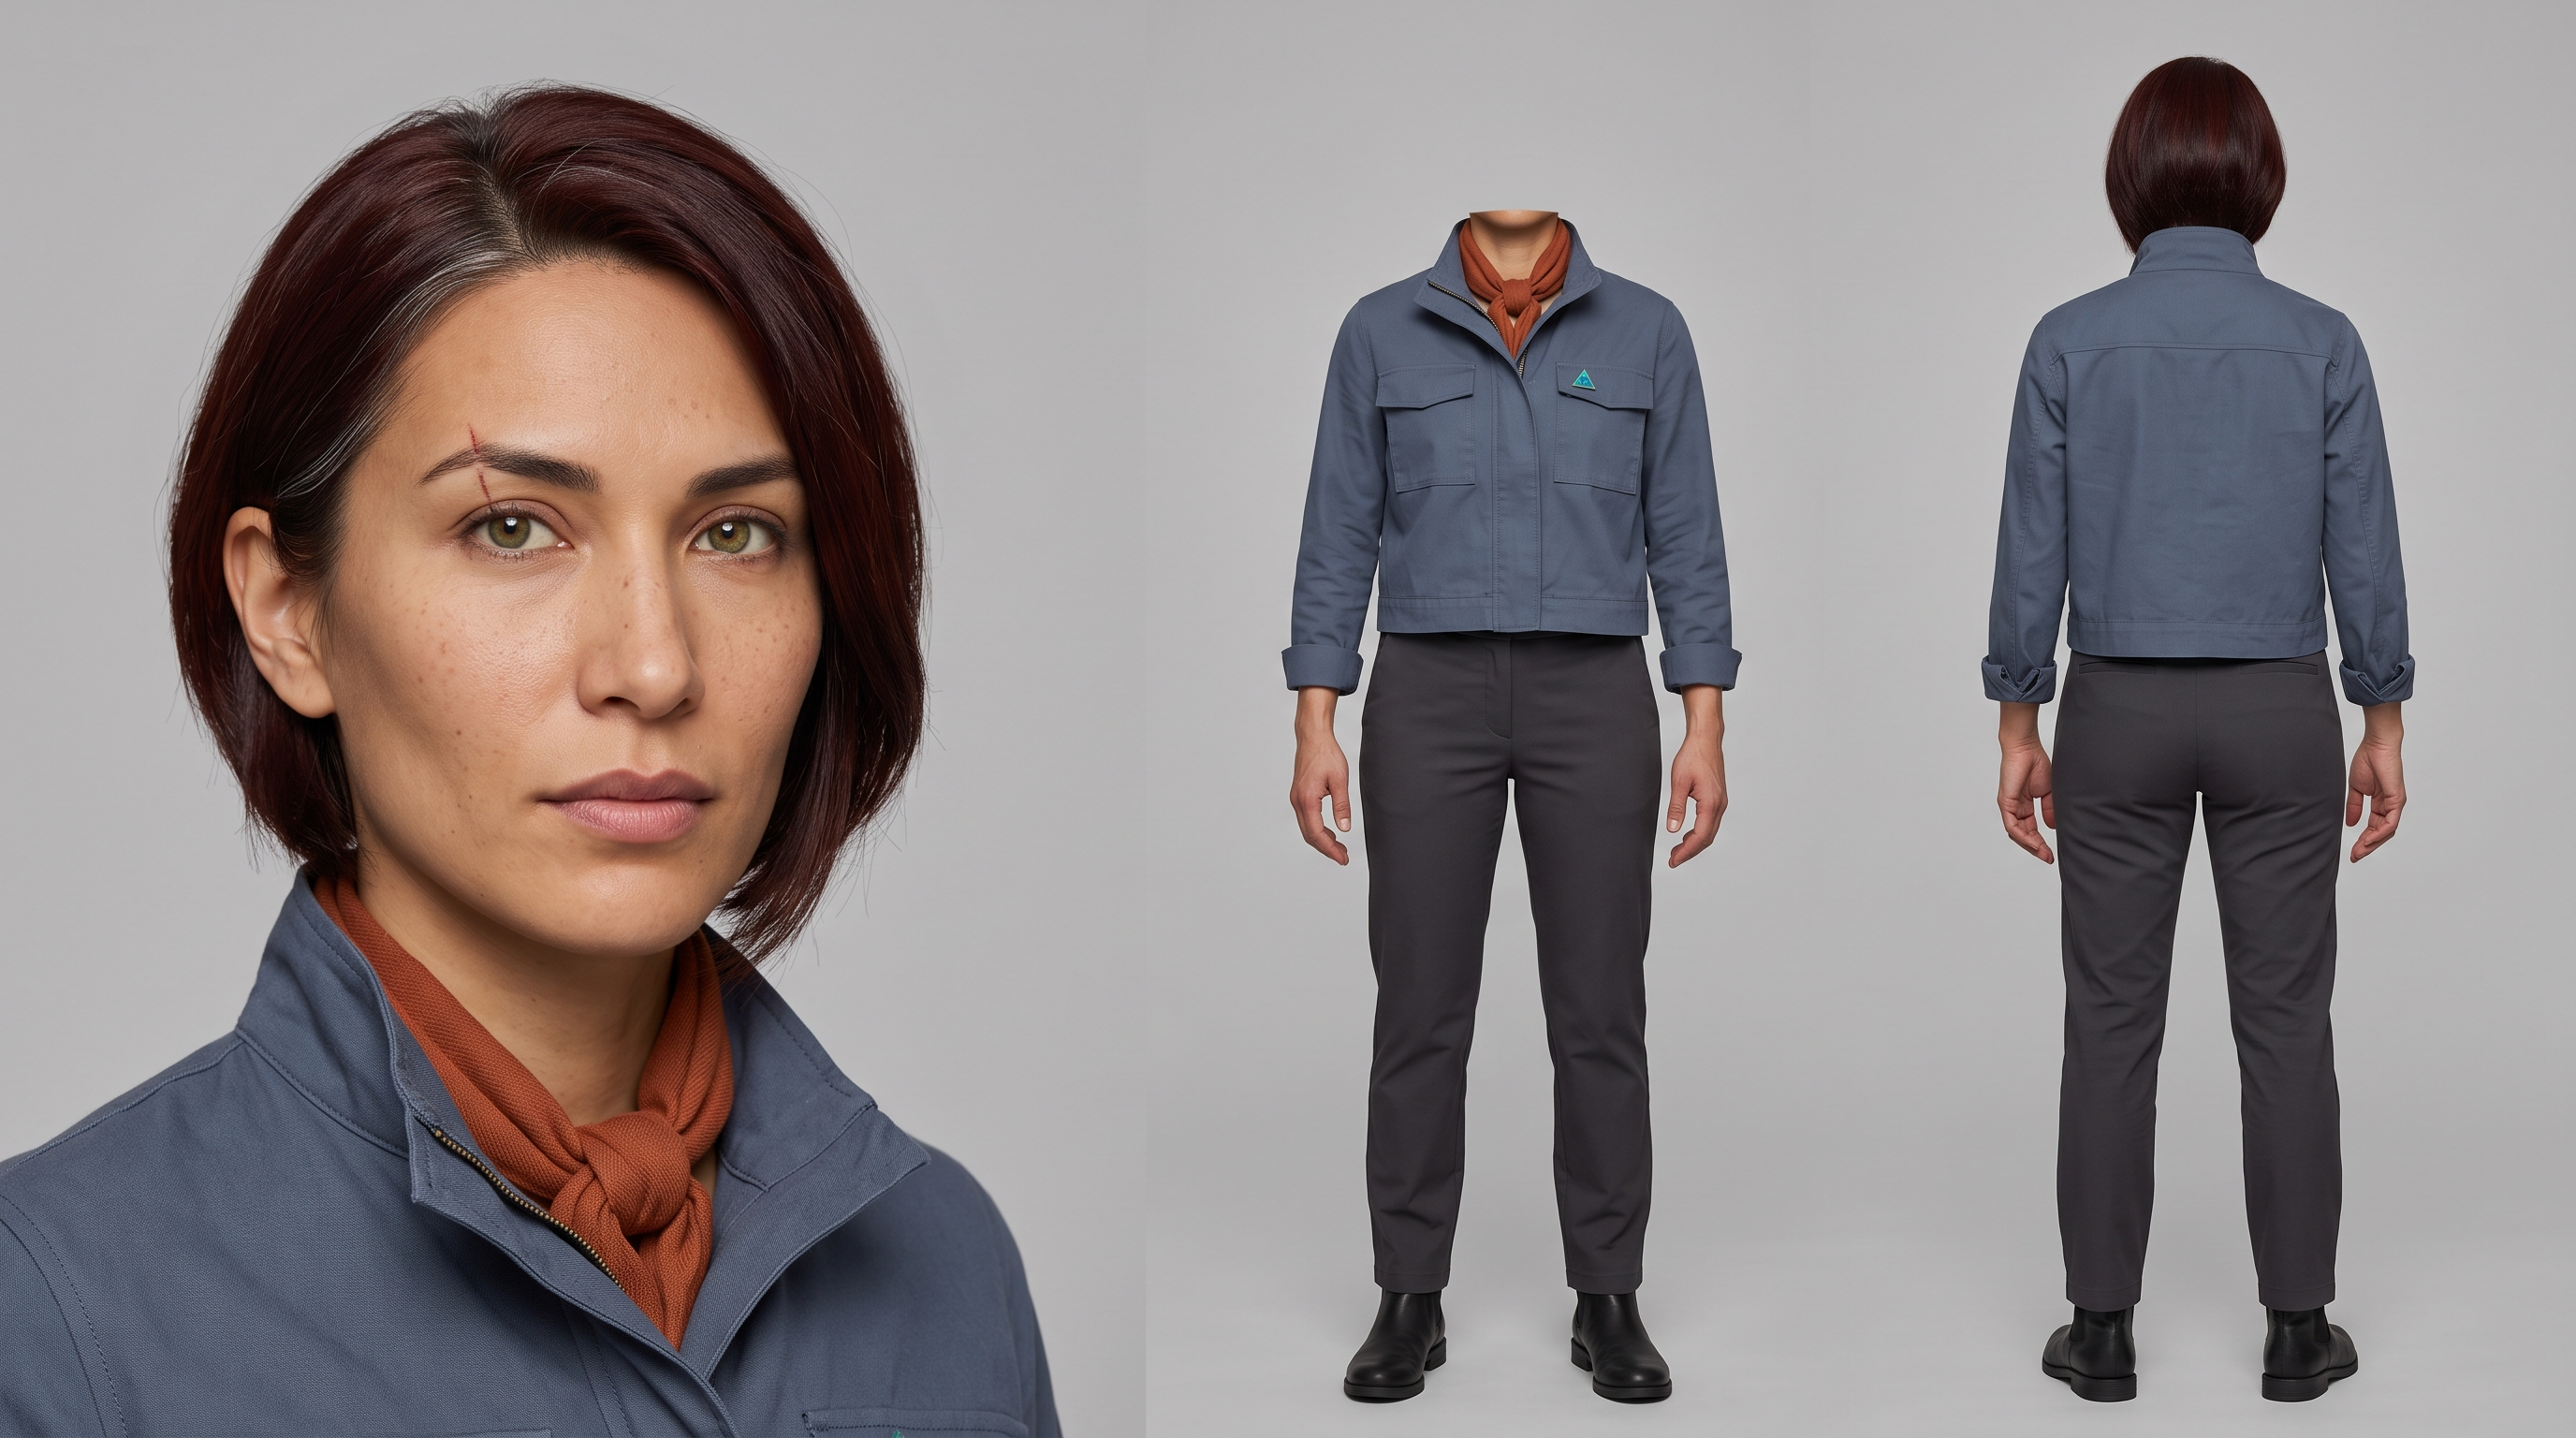
One approved identity, reused three times.
Nano Banana 2 generated this neutral continuity sheet for 16 credits. The reference locks Mara's authoritative face, body, rear silhouette, hairstyle, slate-blue jacket, orange scarf, and teal pin without forcing the same opening frame into each scene.
Shared voice reference
The same spoken performance guided every model.
We used Ellen, a serious German-accented female stock voice in ElevenLabs v3, at 0.98 speed and natural stability. The final file is 11.28 seconds, short enough for every tested model's audio-reference limit.
[calm] Every place leaves a trace. I map the signal, test the edges, and leave the rest undisturbed. [pause] If the pattern holds, we move before sunset.
speech/elevenlabs-v3 · Ellen · MP3, 44.1 kHz
Test method
One character, one voice, three scene changes.
Every model received the exact Mara continuity sheet and the exact ElevenLabs MP3 as soft image and audio references.
Eleven seconds, three hard cuts, the same locations, actions, camera direction, dialogue, wardrobe rules, and preservation language.
Wan and Seedance rendered at 720p. H3 Max used its nearest native 768p tier. All outputs were 16:9 with generated audio enabled.
Read the controlled prompt
Create an 11-second cinematic sequence with exactly three clean cuts and one recurring fictional character, Mara Vale. Preserve her identity across every shot: warm olive skin, angular oval face, hazel-green eyes, short diagonal scar at the outer left eyebrow, chin-length asymmetrical dark-auburn bob with a narrow silver streak at the left temple, slate-blue cropped utility jacket, burnt-orange scarf, charcoal technical trousers, black ankle boots, and teal triangular pin. Do not change her face, age, hair, wardrobe, body proportions, or accessories between shots. Shot 1, 0-3.5 seconds: dawn on a windswept mountain observation platform. Wide-to-medium view. Mara adjusts a compact field sensor, then looks toward a distant ridge. Slow controlled dolly inward. Shot 2, 3.5-7.5 seconds: hard cut to a dim greenhouse laboratory. Medium profile view. Mara studies a translucent signal map, traces one line with her finger, then glances toward camera. Gentle lateral camera move. Shot 3, 7.5-11 seconds: hard cut to a rocky field at sunset. Medium close-up. Mara lowers a handheld scanner, turns toward camera, and finishes the final line with calm certainty. Subtle push-in. Use IMAGE_REFERENCE as Mara's identity and wardrobe reference. Use AUDIO_REFERENCE as the exact voice, cadence, dialogue, and timing as the exact voice, cadence, dialogue, and timing. Lip-sync Mara naturally when her face is visible. Preserve the original spoken words. No additional dialogue, narrator, music, or captions. Add only restrained location ambience beneath the supplied voice. Natural cinematic lighting, realistic skin and fabric, grounded movement, no glamour retouching, no text or logos.
Only the reference tokens changed: Wan and H3 used Image 1 and Audio 1, while Seedance used @Image1 and @Audio1. The repeated phrase near the end was an input typo and was deliberately left unchanged across all three requests.
Unedited outputs
Watch the three character tests.
01
Best identity consistency
Seedance 2.5
- Cost
- 588 credits · $5.88
- Output
- 11.07 seconds · 720p
- Generation time
- About 9 minutes
What worked
Kept Mara's facial structure, auburn bob, orange scarf, blue jacket, and teal pin most stable through the mountain, laboratory, and sunset scenes. All three requested settings were distinct and readable.
Limitation
The model interpreted some prop actions loosely, and the premium result cost more than the other two videos combined.
video/seedance-2.5 · ByteDance Seedance 2.5 announcement
02
Best value and shot adherence
MiniMax H3 Max
- Cost
- 176 credits · $1.76
- Output
- 11.55 seconds · 768p
- Generation time
- About 30 seconds
What worked
Delivered the clearest three-part structure, retained the canonical jacket, scarf, pin, and haircut, and followed the requested observation-platform composition closely at the lowest video cost.
Limitation
Mara's face became smoother and slightly narrower in the final close-up, and fine identity details such as the eyebrow scar and silver streak were inconsistent.
video/minimax-h3-max · Official MiniMax H3 model card
03
Strong cinematic staging
Wan 3.0
- Cost
- 215 credits · $2.15
- Output
- 11.03 seconds · 720p
- Generation time
- About 4 minutes
What worked
Created coherent environments and natural camera framing while preserving the main wardrobe colors, scarf, haircut, and teal pin across all three scenes.
Limitation
The face drifted most noticeably between the laboratory profile and sunset close-up, changing Mara's jaw, age impression, and facial proportions.
video/wan-3.0 · Alibaba Cloud Wan 3.0 documentation
Measured comparison
Cost, speed, and continuity.
| Model | Identity result | Time | Resolution | Credits | Cost |
|---|---|---|---|---|---|
| Seedance 2.5 | Best identity consistency | About 9 minutes | 720p | 588 | $5.88 |
| MiniMax H3 Max | Best value and shot adherence | About 30 seconds | 768p | 176 | $1.76 |
| Wan 3.0 | Strong cinematic staging | About 4 minutes | 720p | 215 | $2.15 |
Creative Claw sells 1,000 credits for $10. The video comparison used 979 credits. The 16-credit character sheet and ElevenLabs speech generation were separate shared inputs. Generation times are rounded from submission to completed asset and vary with provider load.
What this test does not prove
A consistent outfit is not the same as an identical person.
- We generated one output per model and did not choose the best of several attempts.
- Visual review used sampled frames across each completed clip. The supplied audio was accepted as a reference and every result contains an audio track, but this page does not claim sample-level voice reproduction.
- The character sheet's silver hair streak and eyebrow scar were subtle before video generation, making those details harder to preserve.
- Different native resolution tiers and providers make this a practical workflow comparison, not a laboratory evaluation.
- A custom Voice Design preview was attempted first, but the separate app connector failed before reaching the provider. It was not charged. We used a stock ElevenLabs voice instead.
- Models, pricing, and provider load can change. Check current Creative Claw pricing before a larger production.